Top ETL Tools for Data Engineering: Ranked for Performance & Ease
Data is growing too fast for manual handling. Companies now deal with millions of events daily from apps, websites, and cloud systems.
ETL tools solve this problem. They move, clean, and structure data automatically.
Without ETL tools:
- Data stays scattered across systems
- Reports become slow and inconsistent
- Analytics teams waste time on cleaning instead of insights
Over a quarter of organizations lose more than $5 million annually due to poor data quality
This is why modern companies invest in data engineering services & solutions and data to build strong data pipelines.
This guide breaks down the best ETL tools based on real-world performance and ease of use.
What Is an ETL Tool
ETL stands for Extract, Transform, Load.
Extract
Data is pulled from sources. These are apps, APIs, databases, or CRM systems.
Transform
Data is cleaned and structured. Errors, duplicates, and missing values are fixed.
Load
Clean data is moved into a data warehouse. Examples include Snowflake, BigQuery, or Redshift.
ETL vs. ELT in 2026
The design of data pipelines has fully altered in the past years. ELT is now not a default option. It has become a core part of cloud systems.
Simple flow diagram
ETL flow:
Extract → Transform → Load → Analytics
ELT flow:
Extract → Load → Transform → Analytics
The crucial change is where transformation happens. In ETL, it happens before loading. In ELT, it happens inside the data warehouse.
Defining ETL
ETL means data is cleaned before it reaches the warehouse. It works well when systems are smaller with fixed data rules.
• Data is extracted from sources like apps or databases
• It is transformed in a processing layer
• Then it is loaded into a warehouse for reporting
Defining ELT
ELT gives teams more flexibility because raw data is always available.
• Data is extracted and loaded first in raw form
• Transformation happens inside the data warehouse
• Tools like SQL or dbt handle the transformation layer
ELT for modern cloud systems
Cloud platforms are built for large-scale processing. So, they handle transformations much more efficiently than older ETL systems. ELT is the best choice because:
- Cloud warehouses have high processing power
- Storage is cheaper compared to compute-heavy ETL layers
- Teams can reprocess raw data anytime without re-extraction
- It supports faster iteration for analytics and machine learning
Modern data stack example
A common 2026 architecture looks like this:
| Layer | Tool | Role |
| Ingestion | Fivetran | Moves data from sources to warehouse |
| Warehouse | Snowflake | Stores raw and structured data |
| Transformation | dbt | Builds models and cleans data |
| BI Layer | Power BI / Looker | Creates dashboards and reports |
When to choose ETL
Choose ETL when:
- Data needs strict validation before storage
- You are working with legacy systems
- Compliance rules require pre-processed data
- Data volume is relatively small
When to choose ELT
Choose ELT when:
- You use cloud data warehouses
- You need fast and flexible analytics
- Data volume is large or growing quickly
- You want to support AI and machine learning pipelines
How We Ranked These ETL Tools
We evaluated each tool using practical business needs like:
- Performance: Speed of data processing and scalability
- Ease of use: Setup time and learning curve
- Integrations: Support for databases, APIs, SaaS tools
- Cost efficiency: Pricing vs features
- Real-world usage: Startup, mid-size, and enterprise suitability
Comparison Table of Top ETL Tools
Different tools serve different needs. The table below expands the comparison so you can see what fits your use case.
| Tool | Connector Count | Pricing Start | Deployment | Type (ETL / ELT / Hybrid) | Best For |
| Fivetran | 500+ | Paid (usage-based) | Cloud | ELT | Fully automated pipelines and analytics teams |
| Stitch | 100+ | Free tier available | Cloud | ETL | Beginners and small teams |
| Informatica | 1000+ | Enterprise pricing | Cloud + On-prem | Hybrid | Large enterprises with complex systems |
| Airbyte | 350+ (community growing) | Free (open-source) | Cloud + Self-hosted | ELT | Engineering teams needing flexibility |
| AWS Glue | N/A (AWS-native integrations) | Pay-as-you-go | Cloud | ETL / ELT | AWS-based data ecosystems |
| Azure Data Factory | 90+ connectors | Pay-as-you-go | Cloud | Hybrid | Microsoft ecosystem users |
| Google Cloud Dataflow | Limited native connectors | Usage-based | Cloud | ELT | Real-time streaming and GCP users |
| Talend | 1000+ | Subscription-based | Cloud + On-prem | Hybrid | Data governance and integration-heavy workflows |
| Matillion | 50+ | Paid SaaS | Cloud | ELT | Cloud warehouse-centric teams |
| Hevo Data | 150+ | Paid plans | Cloud | ELT | No-code pipeline setup for fast deployment |
| Pentaho | 300+ | Open-source + enterprise | On-prem + Cloud | ETL | Traditional ETL and legacy systems |
| Oracle Data Integrator | 200+ | Enterprise pricing | On-prem + Cloud | ETL | Oracle-heavy enterprise environments |
Build Data Pipelines That Scale With Your Business
Best Overall ETL Tools for Data Engineering (Top Tier)
These tools are widely used in production systems.
Fivetran
Fivetran is a fully managed ETL platform. It offers:
- No-code setup
- Automatic schema handling
- Strong reliability for large pipelines
Suited for: Teams that want automation without maintenance effort.
Airbyte
Airbyte is an open-source ETL tool. It has:
- Large connector library
- Flexible customization
- Strong engineering control
Suited for: Teams that want full control over data pipelines.
Informatica
Informatica is an enterprise-grade platform. It provides:
- High scalability
- Advanced governance features
- Strong security controls
Suited for: Large organizations with complex data systems.
Best ETL Tools for Cloud Data Engineering
Below is a deeper look at the most widely used cloud ETL tools.
Fivetran (Cloud-first)
Fivetran is designed to remove most manual work from data pipelines. This lets teams to focus on analytics instead of maintenance.
Key details
- Connector count: 500+ prebuilt connectors
- Pricing: Starts around $500/month for 1M monthly active rows (usage-based model)
- Deployment: Fully cloud-based
- Type: ELT-focused
Pros
- Very low maintenance after setup
- Strong reliability for production pipelines
- Excellent integration with cloud warehouses
Cons
- Pricing can increase quickly with high data volume
- Limited customization compared to open-source tools
AWS Glue
AWS Glue is Amazon’s serverless ETL service. It is built for scalable data processing inside the AWS ecosystem. AWS Glue is commonly used in data lake and big data architectures.
Key details
- Connector count: 70+ native integrations (plus custom connectors)
- Pricing: Around $0.44 per DPU-hour (varies by region and usage)
- Deployment: Fully serverless cloud service
- Type: ETL and ELT support
Pros
- Fully managed and serverless
- Deep integration with AWS services like S3 and Redshift
- Scales automatically with workload
Cons
- Requires AWS expertise for advanced setups
- Debugging jobs can feel complex for beginners
Azure Data Factory (ADF)
ADF is Microsoft’s cloud-based ETL and data integration service. It is used in enterprises that rely on Microsoft tools.
Key details
- Connector count: 90+ built-in connectors
- Pricing: Pay-as-you-go, based on pipeline runs and activity usage
- Deployment: Cloud + hybrid support
- Type: Hybrid ETL/ELT
Pros
- Strong integration with Power BI and Azure ecosystem
- Good hybrid cloud support for legacy systems
- Visual pipeline builder is easy to use
Cons
- Can become expensive at scale
- Advanced transformations may require additional tools like Databricks
Google Cloud Dataflow
Google Cloud Dataflow is a fully managed service for stream and batch processing. It is built on Apache Beam and is designed for real-time analytics at scale.
Key details
- Connector count: Limited native connectors, relies on GCP ecosystem
- Pricing: Based on compute usage (streaming and batch processing units)
- Deployment: Fully cloud-based
- Type: Real-time streaming + batch processing
Pros
- Excellent for real-time and streaming pipelines
- Strong integration with BigQuery
- Highly scalable for large workloads
Cons
- Steeper learning curve compared to ETL-only tools
- Works best within GCP ecosystem, less flexible outside it
AI-Powered ETL and 2026 Trends in Data Engineering
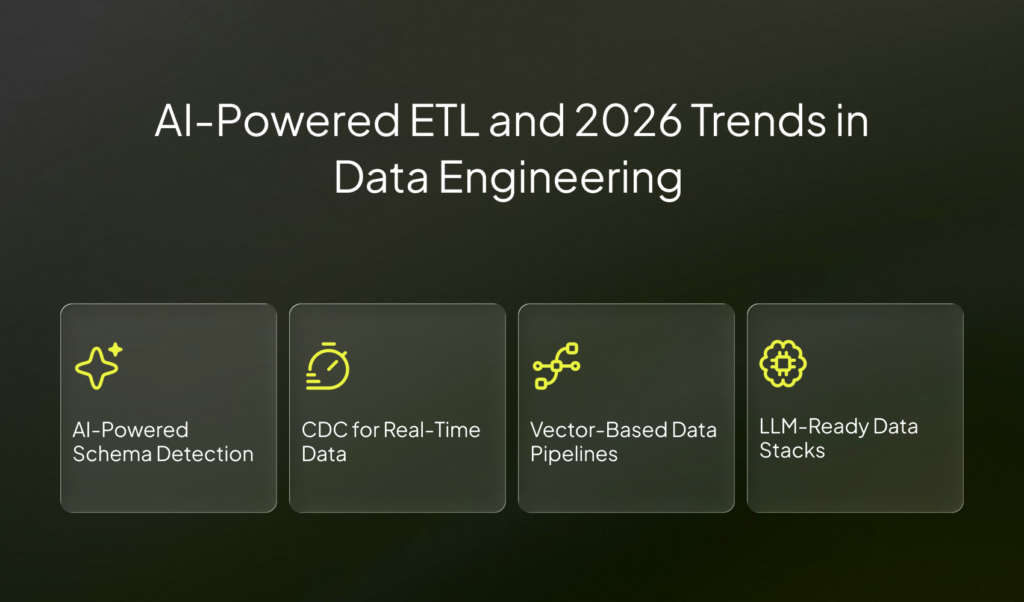
In 2026, ETL tools are becoming smarter and more automated. This is because of in-built AI into the pipeline.
AI-powered schema detection is becoming standard
Earlier, engineers had to manually define data structures. That is changing now.
AI-based ETL tools can:
- Automatically detect schema changes in source systems
- Adjust pipelines without breaking dashboards
- Reduce manual mapping work for engineers
This is especially useful in fast-changing eCommerce systems. Here, product and customer data changes frequently.
Change Data Capture (CDC) is now core to real-time pipelines
CDC is now a default feature in most modern ETL platforms. It helps by:
- Capturing only changed data instead of full datasets
- Reducing processing time and cloud cost
- Enabling near real-time analytics
Vector embeddings are shaping new data pipelines
A major shift in 2026 is the rise of AI and LLM-based systems. ETL pipelines are now being used for:
- Storing embeddings from text, images, and product data
- Feeding vector databases for semantic search
- Supporting recommendation systems and AI assistants
LLM-ready data stacks are becoming common
Companies are now preparing data not just for AI models. Modern pipelines now support:
- Clean structured data for analytics
- Unstructured data for LLM training
- Hybrid data flows combining both
Data engineering consulting services design AI-ready pipelines that requires specialized architecture planning.
Which ETL Tool Should You Choose? (Based on Use Case)
Different companies need different tools.
Startups
Start with simple and low-cost tools.
- Airbyte
- Stitch
Mid-sized companies
Need balance between control and automation.
- Fivetran
- Azure Data Factory
Enterprises
Need security and governance.
- Informatica
- AWS Glue
Data-heavy companies
Need real-time pipelines.
- Google Cloud Dataflow
Final Recommendation: Best ETL Tools Ranked Summary
Here is a simple final ranking:
- #1 overall tool: Fivetran
- Best for beginners: Stitch
- Best for enterprises: Informatica
- Best open-source option: Airbyte
- Best cloud-native option: AWS Glue
Most companies also combine tools with data engineering consulting services to design scalable architectures.
Pricing Breakdown of Popular ETL Tools
Below is the pricing breakdown based on publicly available vendor information.
| Tool | Pricing Model | Starting Price | Notes |
| Fivetran | Usage-based (MAR model) | Around $500/month for 1M Monthly Active Rows | Pricing increases with data volume |
| Airbyte | Open-source + Cloud | Free (self-hosted), Cloud starts around $10/month | Cloud pricing depends on usage |
| Hevo Data | Subscription-based | Starts around $239/month | Includes managed pipelines |
| Stitch | Subscription-based | Starts around $100/month | Simple pricing for small teams |
| Matillion | Usage-based SaaS | Custom pricing (typically mid to high range) | Best for cloud warehouses |
| AWS Glue | Pay-as-you-go | Around $0.44 per DPU-hour (varies by region) | Charges based on compute usage |
| Azure Data Factory | Pay-per-use | Around $1 per 1,000 runs (varies) | Pricing depends on pipeline activity |
| Google Cloud Dataflow | Usage-based | Varies by processing units | Best for streaming workloads |
| Informatica | Enterprise licensing | Custom pricing (often $1000s/month) | Designed for large enterprises |
| Talend | Subscription + enterprise | Starts mid-range, varies by edition | Strong governance features |
Need an AI-ready data stack?
Similar Posts

Why Modern Data Engineering is the Backbone of Digital Transformation
Modern data engineering is the backbone of digital transformation because clean and reliable data is the lifeline of every digital system. Every digital product needs it to deliver real results. Without it, transformation stays stuck at the surface level. Apps look modern, but decisions stay slow. Tools multiply, but insight stays shallow. That is the […]...
Data Engineering vs. Data Analytics: What Your Business Needs First
Data engineering and data analytics are often used together. But they are not the same. One prepares the data. The other uses it to make decisions. Many businesses struggle to decide where to invest first. Should you fix your data systems or start building reports? This guide gives you a clear answer to the one […]...